






A unified data platform doesn't automatically simplify a real estate data stack. It simplifies the stack only when it owns ingestion, identity resolution, governance, and delivery end to end. That distinction matters because the migration failures happen in the gaps between those layers, not in the architecture diagram.
The market is already moving toward consolidation. The broader data management platform market was estimated at USD 2.51 billion in 2024 and is projected to reach USD 7.02 billion by 2033, at a 12.2% CAGR from 2025 to 2033. North America accounted for over 35.0% of regional revenue in 2024, which reflects where enterprise demand has concentrated first. Market context for data management platforms
For property companies, the business case is straightforward:
- One governed property record: Replace disconnected feeds, spreadsheets, and point integrations with standardized entities.
- Fewer handoffs: Keep raw data, transformations, lineage, and delivery inside one operating model.
- Better activation: Serve underwriting, valuation, portfolio monitoring, and CRM workflows from the same governed data.
- A controlled migration: Treat audit, pilot, parallel run, and cutover as separate engineering stages.
The right platform won't eliminate complexity. It will put complexity in the right place, where engineers can observe, govern, and fix it before an underwriter or customer sees the damage.
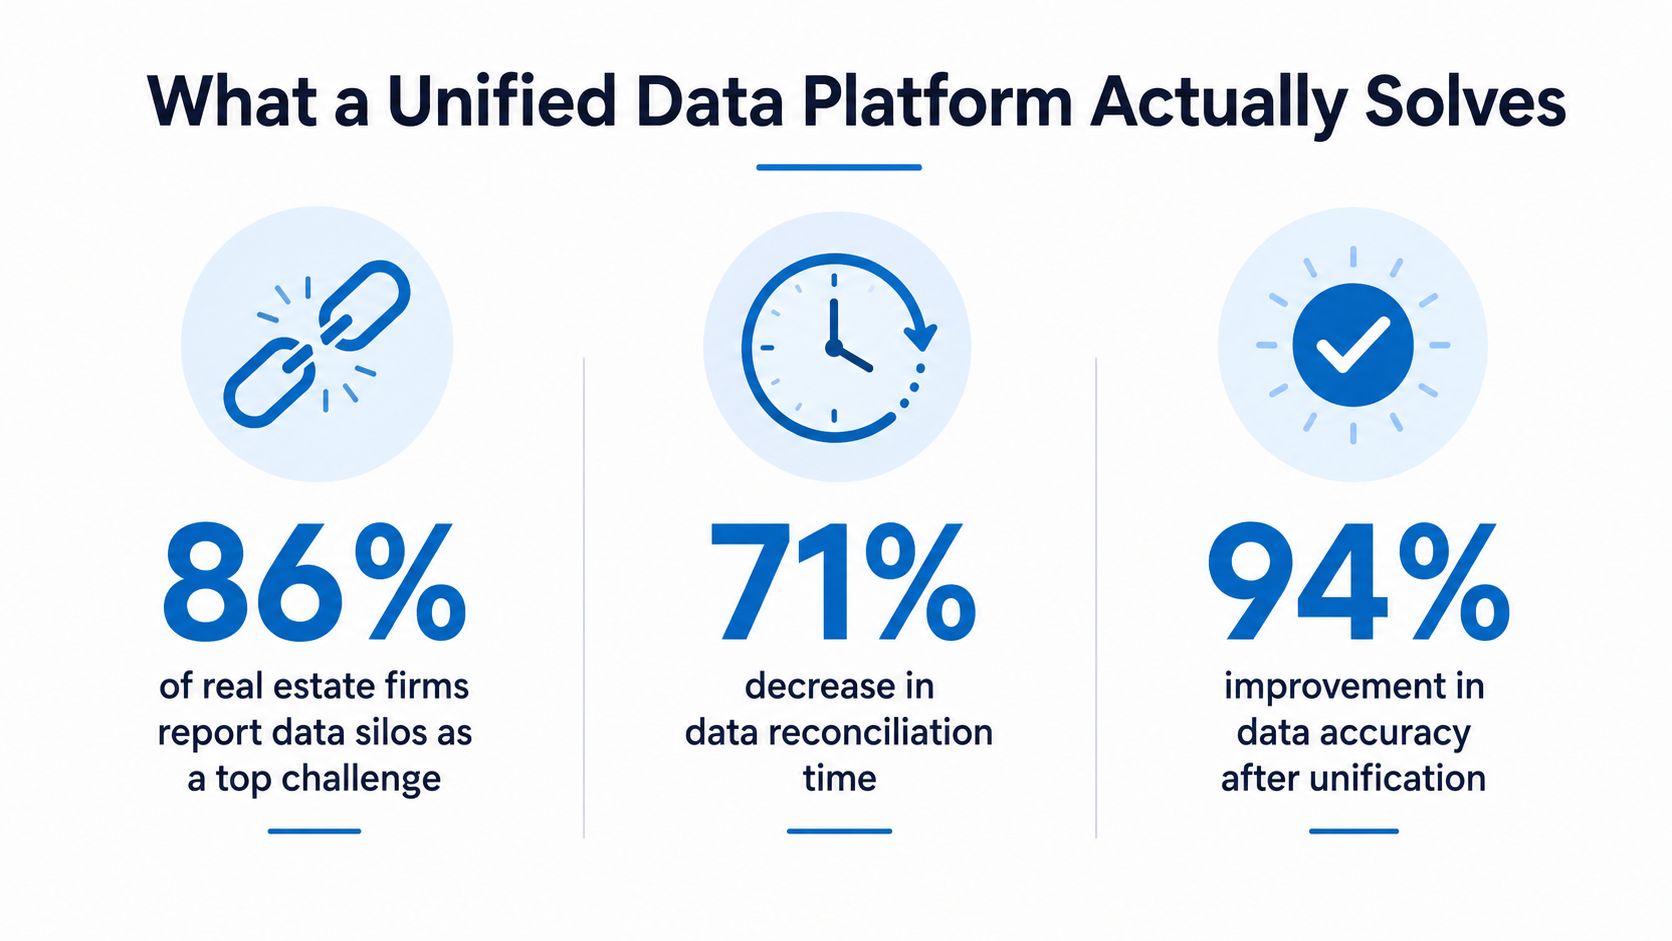
What a Unified Data Platform Solves
A unified data platform simplifies a real estate data stack only when it controls ingestion, identity resolution, governance, and delivery end to end. The migration risk sits between those layers. A diagram can show connected boxes while engineers still reconcile property identities, repair broken handoffs, and explain stale records to business users.
Real estate firms commonly run MLS scrapers, county CSV feeds, assessor systems, CRM exports, underwriting spreadsheets, and point APIs on separate schedules. Each system holds a partial property record. Without shared identifiers and update rules, downstream teams make their own decisions about which version to trust.
That inconsistency creates business failures, not just technical inconvenience. Property data requires consistent addresses, parcel relationships, ownership logic, transaction history, and refresh timing. A bad handoff can produce a missed lien, duplicate prospect, incorrect valuation input, or underwriting review based on stale information. With property datasets exceeding 155M records and daily updates, slow movement between systems turns migration debt into operating cost.
Adoption indicators show why integration is now an operating requirement. 78% of enterprises reported using data integration tools in 2023, 65% had adopted hybrid data integration approaches by 2024, and, as a 2022 baseline, only 28% had achieved full integration across silos. Progress since that baseline has been incremental. In the same research, 62% of enterprises integrated data from more than 10 sources in 2023, while 75% said data integration was part of their core strategy. Enterprise data integration adoption indicators
For a property business, unification must standardize records before a model or application consumes them:
- Capture source records from county, MLS, assessor, recorder, and market systems.
- Resolve entities across APNs, addresses, parcels, owners, and organizations.
- Apply quality rules that expose missing, conflicting, and stale attributes.
- Expose governed outputs to underwriting, pricing, lead routing, and portfolio systems.
Practical rule: If an analyst must reconcile identifiers before using the data, the platform has not unified it. It has relocated the reconciliation work.
Use a defined data validation workflow to test whether malformed, incomplete, and conflicting property attributes are caught before activation. Measure reconciliation time, failed records, and freshness during the migration, not only after cutover.
A unified platform is more than a storage destination. It places ingestion, storage, processing, governance, analytics, and activation under one operating model. Microsoft guidance recommends governed access to enterprise data instead of direct or ad hoc application paths, because standardized integration and centralized policy enforcement improve consistency, auditing, and reuse. Microsoft guidance on governed enterprise data access
Unified vs Federated vs Data Mesh vs Best of Breed
The architecture choice determines where property-data complexity accumulates. A unified platform centralizes the operating model, a federated layer leaves data in place and queries across systems, data mesh distributes ownership by domain, and a warehouse-plus-tools stack assembles specialist products.
| Dimension | Unified Platform | Federated Query | Data Mesh | Warehouse + Tools |
|---|---|---|---|---|
| Governance | Central policy, lineage, and access model | Policies must span systems | Federated computational governance | Governance varies by tool |
| Latency | Predictable for curated workloads | Cross-source joins add overhead | Depends on domain implementation | Handoffs can add delay |
| Cost | Consolidated platform spend | Query and connector costs remain | Requires domain ownership and enablement | Integration and maintenance debt grows |
| Scalability | Scales ingestion, processing, and delivery together | Scales queries, not necessarily source pipelines | Scales ownership across domains | Each component scales differently |
| Real estate fit | Strong for property records and mixed delivery | Limited for join-heavy county workloads | Strong only with staffed domains | Works for mature engineering organizations |
Federation looks elegant on an architecture slide. It becomes less attractive when an application needs to join property, parcel, ownership, mortgage, and transaction data across systems with different schemas and refresh schedules. Lakehouse research reports that federated architectures introduced 8% to 27% overhead on 100TB datasets, depending on query complexity and geographic distribution. Centralized lakehouses recorded 3.2-second P50 latency versus 3.5 seconds for federated setups, and 12-second 95th percentile latency versus 13.5 seconds. Lakehouse and federated architecture benchmarks
That performance tax matters when a property platform serves both batch consumers and interactive APIs. A federated query layer can remain useful for selective access to external systems, but it shouldn't become the default path for common property joins.
Where the alternatives break
- Federated query: It avoids immediate migration, but cross-county joins can become expensive, slow, and difficult to troubleshoot.
- Data mesh: Its principles are domain-oriented ownership, data as a product, self-serve infrastructure, and federated governance. The model is sound, but property teams often lack the staffing and operating discipline to own every domain product. One published review reports 60% to 80% reductions in data-product delivery time and a 45% improvement in data-quality scores, but those findings shouldn't be treated as an automatic result of adopting mesh architecture. Data mesh principles and reported outcomes
- Warehouse plus tools: This is a reasonable choice for an organization with an established warehouse, strong data engineering, and mature governance. For everyone else, separate ingestion, transformation, quality, catalog, API, and activation products create integration debt.
- Unified platform: It owns the path from source capture through normalization and delivery, which is the critical advantage for real estate workloads.
My recommendation is direct: choose a unified architecture for property data unless the buyer already operates a mature warehouse with dedicated data engineering headcount. Use federation selectively. Don't choose data mesh because the terminology sounds modern. Don't assemble a best-of-breed stack until the team has priced the long-term cost of connecting and governing every component.
Core Components Inside a Real Estate Unified Stack
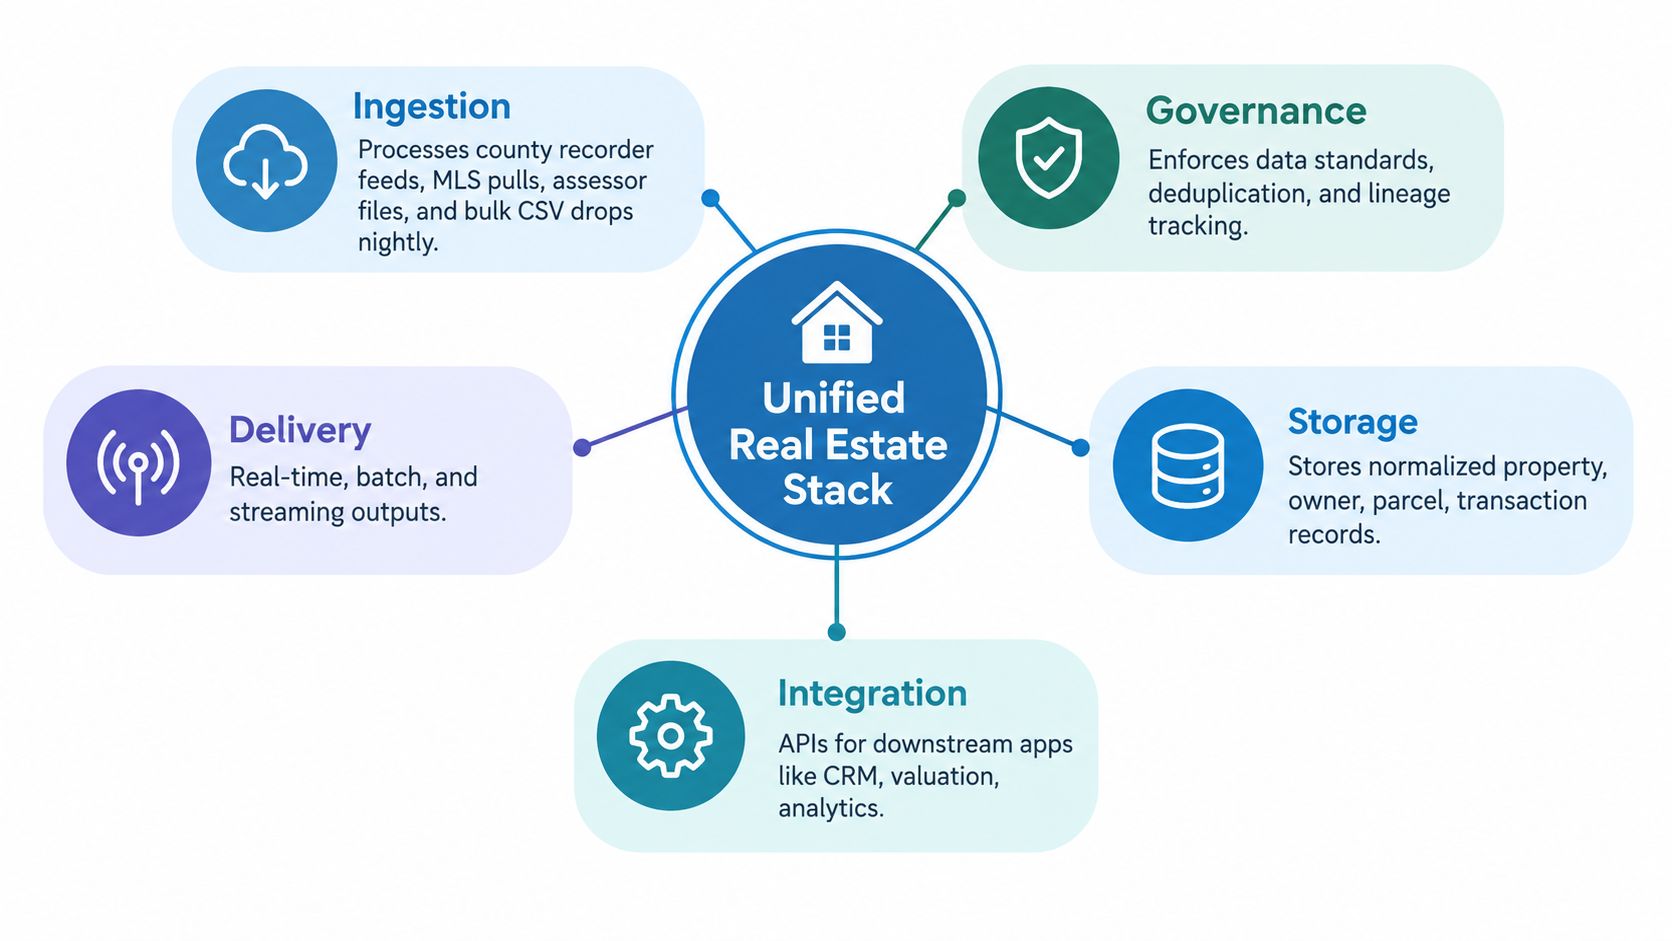
A real estate unified stack needs five capabilities working as one system: ingestion, storage, processing, governance, and activation. Each capability should operate against large property datasets without forcing the engineering team to bolt on another pipeline.
Ingestion
Ingestion captures county recorder feeds, MLS pulls, assessor files, APIs, and bulk CSV drops. The platform should support nightly loads and intra-day updates while preserving source timestamps, source identifiers, and failure states.
A successful ingestion layer doesn't just accept files. It validates schema changes, quarantines malformed records, retries failed transfers, and records which source supplied each attribute. Without those controls, a new county export can inadvertently alter field meanings or erase values downstream.
Storage
Storage should preserve raw source records and maintain a normalized entity layer. The normalized layer needs durable keys for APNs, addresses, parcels, and owner identities, while retaining the raw values needed for audit and dispute resolution.
A lakehouse-style core is usually the right default because property workloads combine structured records, semi-structured source files, historical snapshots, and machine-learning features. A governed storage and compute layer reduces movement between separate analytical domains, while curated serving layers protect user-facing APIs from expensive exploratory queries.
Processing
Processing turns source records into usable property entities. The pipeline should handle:
- Deduplication: Detect repeated parcel and transaction records.
- Geocoding: Standardize location data and support spatial relationships.
- Parcel matching: Connect parcel boundaries, situs addresses, and mailing addresses.
- Ownership resolution: Link individuals, businesses, trusts, and related ownership records.
- Attribute normalization: Standardize dates, amounts, statuses, and categorical values.
Processing must be repeatable. If the same source arrives again, the result should be deterministic and traceable rather than dependent on a manual spreadsheet correction.
Governance and activation
Governance assigns lineage, refresh expectations, confidence scores, access policies, and ownership to each attribute. A reference architecture for unified multi-cloud AI data platforms treats governance as a structural requirement because operational systems, lakes, warehouses, AI pipelines, and BI tools all share the same governed foundation. Reference architecture for governed multi-cloud AI data platforms
Activation delivers the resulting record through REST APIs, GraphQL, bulk S3 drops, Snowflake shares, and webhook streams. Underwriters may need a queryable property profile, portfolio teams may need a nightly extract, and CRM systems may need event-driven updates. Those consumers shouldn't each rebuild the same joins.
Identity resolution is the layer many teams underestimate. Read the identity resolution API documentation and test whether its matching behavior is explainable, reversible, and suitable for your own entity model.
Enterprise Requirements That Make or Break a Platform
Enterprise requirements should be treated as pass or fail gates, not as a feature checklist. A polished demo means little if the platform can't preserve coverage, lineage, and delivery reliability across a property portfolio.
| Requirement | Pass Criterion | Fail Signal |
|---|---|---|
| Scalability | Handles the full property footprint and daily refreshes without material degradation | Performance falls off as record volume grows |
| Accuracy | Demonstrates documented matching and normalization quality across parcel, APN, and address data | Vendor provides no test methodology or coverage evidence |
| APIs | Supports governed REST and GraphQL access for operational applications | API responses depend on manual exports or undocumented limits |
| Bulk delivery | Supports SFTP, S3, and Snowflake delivery for portfolio loads | Consumers must build their own extraction pipelines |
| Governance | Provides lineage, PII masking, consent tracking, and auditability | Teams cannot trace fields back to sources |
| Security | Provides SOC 2 Type II controls, encryption, and role-based access | Security claims lack certification or implementation detail |
The six gates
Scalability comes first. Test ingestion, transformation, indexing, and serving against the complete property footprint, not a sanitized demo sample. The platform should maintain predictable behavior when county refreshes overlap with API traffic and model jobs.
Accuracy needs record-level evidence. Ask for match methodology, exception handling, source coverage, and confidence scoring for APNs, addresses, owners, and parcels. A single accuracy number without field-level definitions is not useful.
APIs must support the actual consumer workflow. Underwriting applications need property, ownership, mortgage, valuation, and distress attributes without forcing developers to assemble several endpoints and reconcile inconsistent identifiers.
Bulk delivery matters because portfolio systems often work in scheduled loads. Require secure delivery through the storage and warehouse environments your team already operates.
Governance and security cannot be added after launch. GDPR and CCPA workflows, PII masking, encryption in transit and at rest, role-based access, lineage, and audit logs belong in the initial design.
A platform that passes a demo but fails a record-level audit is not enterprise-ready.
Real Estate Use Cases and ROI in Practice
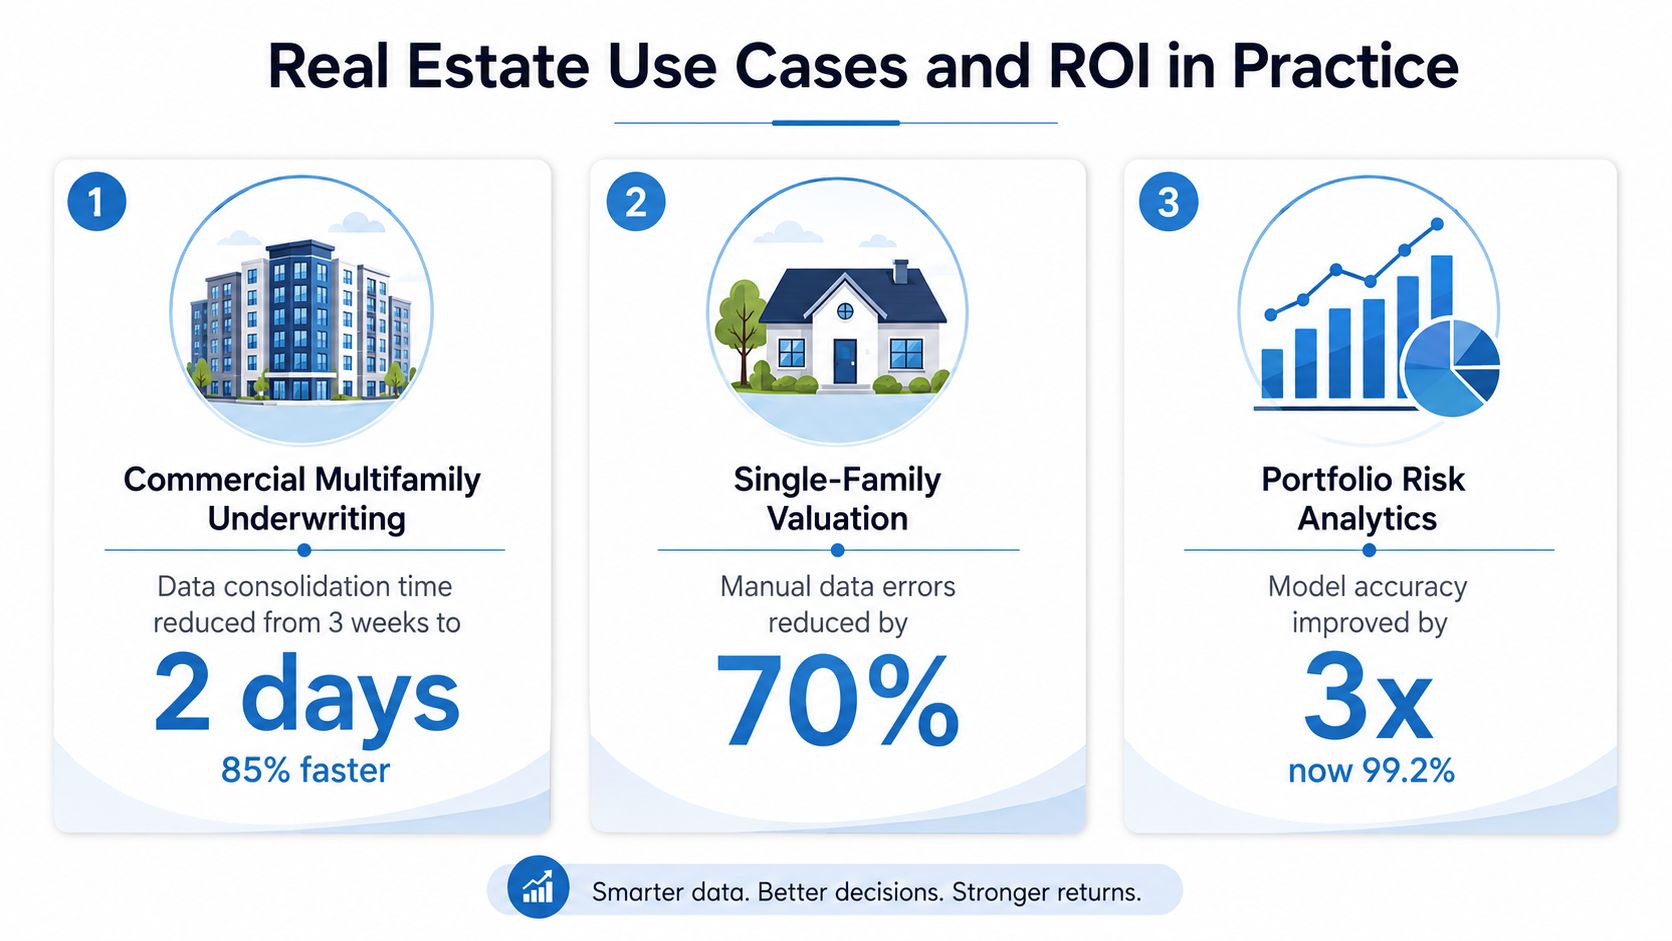
A unified property data platform earns its keep by removing reconciliation work from decisions that repeat every day. Underwriting, portfolio monitoring, and lead generation benefit first because each joins records that usually sit in separate systems. The ROI case should be measured in hours removed, decisions accelerated, and errors prevented, not in a vendor's headline promise.
Public, verified case studies with specific ROI figures for unified property data platforms are scarce. Treat vendor claims as hypotheses to test against your own portfolio, using the same records and business conditions that your team handles in production.
Commercial underwriting
A multifamily underwriting workflow may combine assessor records, MLS information, rent comparables, ownership data, mortgage signals, and distress indicators. A unified platform standardizes those inputs before analysts build a deal view, exposes exceptions, and preserves the evidence behind material assumptions.
Consider a portfolio team monitoring 50,000 properties that spends 20 analyst-hours each week reconciling county and MLS feeds. An automated pipeline with ownership resolution does not eliminate review. It changes the task to checking flagged exceptions. That scenario gives the team a concrete baseline for measuring recovered capacity, faster diligence, and fewer avoidable underwriting errors.
Track the workflow at three points:
- Source readiness: How long does it take to assemble the required records?
- Analyst reconciliation: How much time goes into resolving conflicting identifiers?
- Decision traceability: Can the team show the source and transformation history for each material input?
Run the platform against real acquisition files before claiming savings. Test the full property footprint, because 155M+ records and daily updates expose slow movement that a small pilot can hide.
Portfolio monitoring
Portfolio monitoring requires recurring updates rather than a one-time data pull. Tax, ownership, mortgage, valuation, listing, and distress changes should enter a normalized portfolio view with timestamps and confidence indicators.
Risk teams can define events such as ownership changes, delinquency signals, valuation movement, or new distress activity. A dashboard alone has little value. The system must identify the changed record, explain the change, and route the event to the correct operator without forcing analysts to compare separate extracts.
Lead generation
Lead generation combines property characteristics with ownership and intent signals. A unified record lets marketing teams segment by absentee ownership, equity position, property type, mortgage status, and recent activity without exporting lists through incompatible tools.
Measure contactability, segment eligibility, routing time, and downstream conversion through a controlled comparison. Audience definitions should be reproducible, restricted records should be suppressed, and each selected attribute should retain its lineage.
Review enterprise Snowflake success examples, then test whether the vendor can separate governed data operations from downstream consumption in your architecture.
Establish a baseline, define the source population, document exclusions, and compare the unified workflow with the existing process under matching conditions. That measurement discipline matters more than a promised lift.
Vendor Selection Checklist for Property Data Platforms
Select a vendor with a weighted scorecard, not a glossy product tour. The criteria below reflect what property teams need from a unified data platform.
| Criterion | Weight | Pass Threshold | BatchData Benchmark |
|---|---|---|---|
| Data coverage | 20% | Clear county and source coverage | 155M+ U.S. property records across 50+ sources |
| Accuracy and match rate | 15% | Documented field-level matching | Demonstrated through custom testing |
| Latency and freshness | 10% | Meets API and refresh requirements | Daily updates and low-latency access |
| API and bulk delivery | 10% | REST, GraphQL, and bulk options | REST, GraphQL, S3, and Snowflake shares |
| Governance and lineage | 10% | Traceable transformations and access controls | Governance tooling and documented workflows |
| Security certifications | 10% | Enterprise security evidence | SOC 2 Type II, GDPR and CCPA tooling |
| Real estate schema depth | 10% | Property, ownership, mortgage, valuation, and distress data | 220+ attributes per parcel |
| Pricing transparency | 5% | Understandable usage and delivery pricing | Require written pricing model |
| Proptech references | 5% | Relevant production references | Validate directly with customers |
| Migration tooling | 5% | Audit, pilot, and parallel cutover support | Dedicated migration services |
BatchData fits this evaluation as one option because it provides 155M+ U.S. property records, daily updates across 50+ sources, 220+ attributes per parcel, REST and GraphQL APIs, S3 and Snowflake delivery, SOC 2 Type II controls, GDPR and CCPA tooling, and migration services organized around audit, pilot, and parallel cutover phases.
The scorecard still needs independent validation. Ask vendors to demonstrate county coverage, show lineage for a sampled field, explain matching exceptions, and provide references from property organizations operating portfolios above 100,000 parcels. Those thresholds are selection tests, not claims that every vendor will meet them.
Red flags that should stop procurement
- Vague coverage: The vendor names regions but won't provide source-level coverage.
- Missing lineage: Users can't identify which source produced an attribute.
- Opaque pricing: Costs change with unclear record, API, or delivery dimensions.
- No migration method: The vendor expects your team to design the cutover alone.
- No relevant references: The vendor can't connect you with comparable production users.
Require a 30-day paid proof of concept before signing a long-term contract. Use your own records, your own edge cases, and your own downstream applications. A vendor that refuses a measurable trial is asking you to finance its uncertainty.
Migration and Implementation Playbook
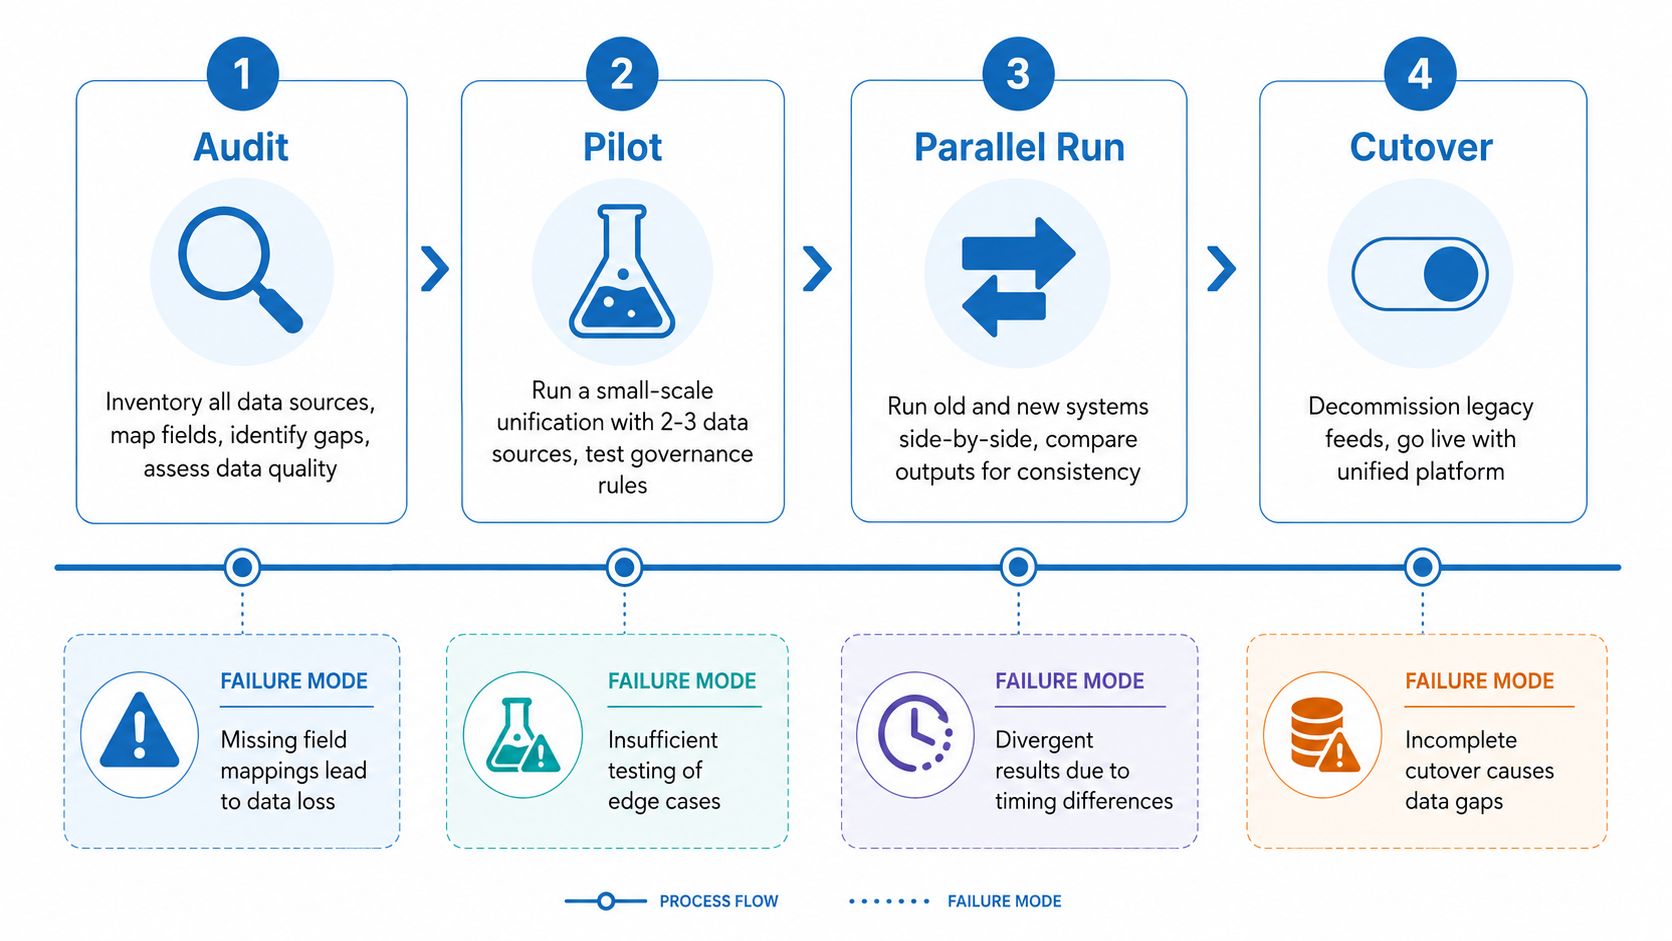
Property-data migration succeeds when teams move in four controlled phases: audit, pilot, parallel run, and cutover. The most expensive mistakes happen when teams skip source inventory or leave the old architecture running indefinitely.
Audit
Inventory every MLS feed, county recorder scrape, assessor file, CSV import, API, spreadsheet, and manual override. Map field-level lineage, identify duplicate parcel identifiers, document refresh schedules, and record which downstream applications depend on each output.
The audit should answer practical questions:
- Which system owns each property attribute?
- Which identifiers connect the same parcel across sources?
- Which transformations happen inside scripts or spreadsheets?
- Which feeds fail?
- Which consumers require batch, API, or event delivery?
If the team can't answer those questions, it isn't ready to migrate.
Pilot
Choose one region or asset class that contains real edge cases. A pilot should test ingestion throughput, normalization rules, identity resolution, governance policies, and delivery behavior against the required refresh cadence.
Don't choose only clean records. Include missing addresses, ownership changes, parcel splits, duplicate APNs, inconsistent county formats, and records that currently require analyst intervention. A pilot that avoids difficult data only proves that the platform works on easy data.
Parallel run
Run the legacy and unified pipelines side by side, compare outputs at record and attribute level, and document every discrepancy. Timing differences are a common source of false failures, so compare source versions and refresh timestamps rather than only final values.
The parallel period must have an exit date. Teams that keep both pipelines alive beyond 90 days risk paying for duplicated storage, duplicated operations, and duplicated incident response. Unified data platform architecture and consolidation context
Cutover
Cut over consumers in dependency order. Start with non-critical reporting, then move portfolio workflows, APIs, underwriting tools, and CRM activation. Define rollback criteria before the switch, especially for coverage gaps, missing attributes, stale records, and unacceptable API behavior.
Post-cutover observability should include record completeness, source freshness, schema changes, match exceptions, API errors, delivery failures, and downstream consumption. Keep the raw source layer available so the team can investigate disputes without restoring the old pipeline.
Use implementation documentation to require explicit ownership for mappings, validation, cutover approvals, rollback decisions, and post-launch monitoring.
Final Decisions Before You Sign the Contract
A CTO should force three decisions before approving a unified data platform.
First, decide whether to build, buy, or co-manage. Compare the vendor contract with the engineering effort required to reproduce broad parcel coverage, source integrations, normalization, matching, governance, and delivery. The relevant cost isn't the first implementation invoice. It's the continuing cost of source maintenance, quality incidents, infrastructure, and on-call coverage.
Second, choose the storage and query pattern deliberately. A lakehouse is the stronger default for mixed batch, analytical, machine-learning, and operational workloads. Federation belongs at the edges, where moving data is impractical or the source remains authoritative. Decide based on ingestion volume, latency requirements, join complexity, and governance rather than architecture fashion.
Third, price lock-in against exit cost. A single vendor can reduce operational burden, but only if contracts protect data portability, export access, schema transparency, and transition assistance. A multi-vendor design can preserve optionality, but it also creates more interfaces to operate and govern.
The next RFPs will emphasize lakehouse convergence, streaming-first activation, open interfaces, and AI-assisted schema mapping. Those trends don't change the procurement rule: prove record-level accuracy on your own portfolio before payment. A platform that can't pass that test won't become trustworthy because its architecture diagram looks modern.
BatchData brings property records, ownership, valuation, mortgage, listing, and distress signals into standardized profiles delivered through APIs and bulk options. Visit BatchData to evaluate a property-data integration against your own records, workflows, and acceptance criteria before you commit to a larger migration.