Most companies don’t have an AI model problem. They have a data foundation problem.
That was the clearest message from a recent multi-speaker discussion on AI-ready data featuring leaders from Insight Software, Reltio, Informatica, and Precisely. Despite different product perspectives, the panel converged on a practical truth: AI succeeds or fails based on whether enterprise data is accessible, trustworthy, governed, and usable in real time.
That matters for every team trying to operationalize property, customer, or operational data. Whether you’re building acquisition workflows, enriching records for outbound campaigns, or powering internal AI agents, the same pattern shows up: data may exist, but it’s often fragmented across systems, stripped of context, and poorly governed for machine-driven decisions.
For BatchData’s audience, this is especially relevant. In real estate and adjacent industries, bad data doesn’t just create messy dashboards. It wastes skip tracing spend, triggers compliance risk, slows lead routing, and causes teams to act on stale or incomplete property intelligence.
This article distills the strongest ideas from the discussion and adds practical context for operators, developers, and data leaders who need to make AI useful in production - not just impressive in a demo.
Key Takeaways
- AI readiness is a data operations challenge first. Models can’t compensate for fragmented, stale, or poorly governed source data.
- Data consolidation is not the same as data unification. Moving records into a warehouse doesn’t resolve duplicates, conflicts, or missing context.
- Governance must happen during data movement, not after. If permissions and policies are applied too late, the AI has already seen what it shouldn’t.
- Context is the missing layer in many AI projects. AI needs meaning, relationships, business rules, and entity resolution - not just rows and columns.
- Real-time delivery matters. A governed answer that arrives too slowly can still break operational workflows.
- Lineage and observability are no longer optional. If an AI agent takes action, teams need to know what data it used and how the output was formed.
- Start with one high-value workflow. Pick a domain like ownership, contactability, or distressed property signals and make it accurate, governed, and repeatable.
- Treat governance as infrastructure. The winning pattern is not more policy documents; it’s embedded controls that make the wrong action hard to take.
The Core Problem: AI Is Being Asked to Operate on Unfinished Data
The panel repeatedly returned to the same gap: organizations are racing to deploy AI on top of enterprise data that was never fully prepared for autonomous use.
That distinction matters.
A human analyst can often spot when something looks off. An acquisition manager might notice that a record has duplicate owners, an outdated mailing address, or a phone number that conflicts with another system. An AI agent typically won’t "notice" in the same way. It will act on whatever context it receives.
That changes the stakes. In earlier analytics eras, poor data quality led to weak reporting. In agentic AI, poor data quality can lead to bad actions:
- contacting the wrong person
- exposing restricted information
- updating the wrong account or record
- triggering outreach based on stale ownership data
- making flawed recommendations that look confident
One speaker framed this well: the issue rarely appears in the demo environment. Demos use clean, controlled data. Production does not.
For real estate and PropTech teams, this is familiar territory. A property dataset may pull from county records, CRM activity, skip tracing outputs, call dispositions, and third-party enrichment layers. If those records aren’t reconciled and governed, any AI workflow built on top of them becomes fragile.
Why "We Put It in the Warehouse" Isn’t Enough
One of the sharpest distinctions in the discussion was between consolidated data and unified data.
A lot of organizations assume that once data lands in Snowflake, Databricks, or another central platform, it’s ready for AI. But central storage does not automatically create a trusted source of truth.
If the same person, property, parcel, or business appears in multiple systems with inconsistent values, simply storing all versions together doesn’t solve the problem. It just centralizes the confusion.
Consolidation gives you access
Unification gives you meaning
That difference is critical in property workflows.
For example, consider a homeowner record that appears across:
- assessor data
- mortgage data
- CRM lead history
- call center outcomes
- DNC screening results
- marketing engagement logs
If those records are not resolved into a coherent entity, AI will struggle with basic questions:
- Is this the same owner across systems?
- Which phone number is safest and most likely to connect?
- Which address is mailing vs. situs?
- Is the owner active, deceased, LLC-managed, or represented by another party?
- Should this lead be suppressed for compliance or surfaced for acquisition?
Without unification, AI doesn’t operate on intelligence. It operates on fragments.
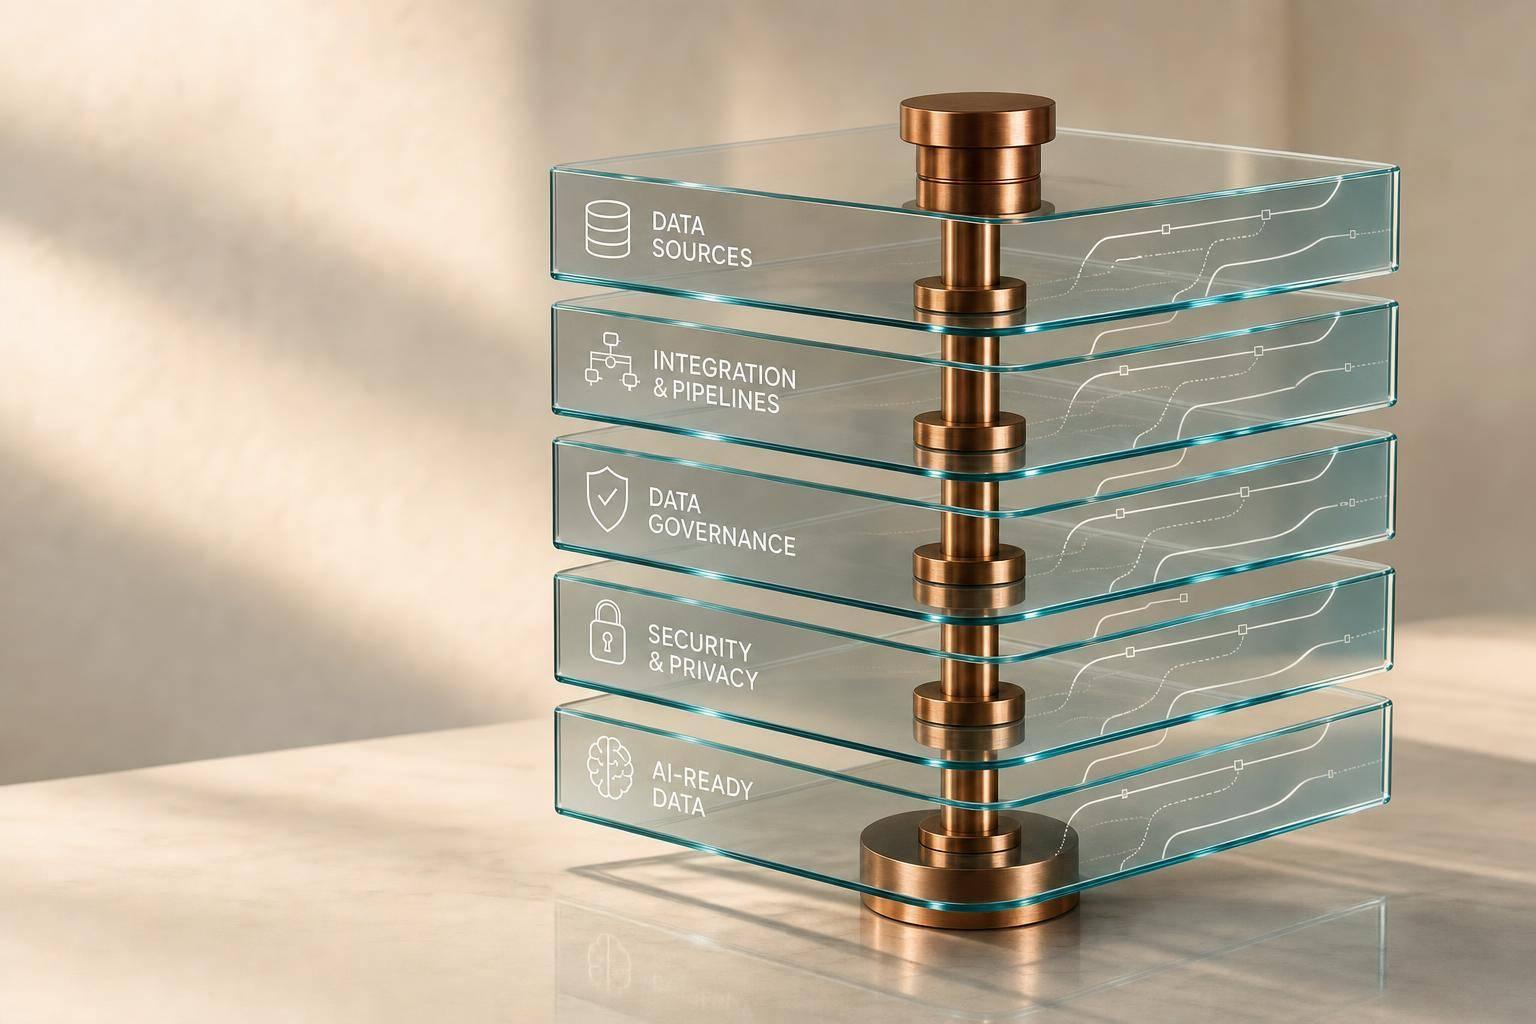
The Five Building Blocks of AI-Ready Data
Across the conversation, five requirements surfaced again and again. Different speakers used different terms, but the pattern was consistent.
1. Access to All Relevant Data
You can’t govern or operationalize data that AI cannot reach.
That sounds obvious, but in practice, the hardest data sources are often the most important: legacy platforms, line-of-business systems, internal spreadsheets, older databases, or disconnected operational tools. In many organizations, the final 20% of connectivity work is what blocks the first 80% of AI value.
For technical teams, this means AI-ready architecture starts with reliable integration - not just APIs on paper, but dependable access to the systems that hold source-of-truth information.
For real estate operators, this includes:
- source property data
- ownership records
- lead and CRM systems
- call outcomes
- suppression lists
- contact intelligence
- transactional and servicing history
If those systems remain siloed, your AI workflow will have blind spots.
2. Data Quality and Preparation
Several speakers emphasized a point data teams have known for years: bad inputs produce unreliable outputs, no matter how advanced the model looks.
Preparation includes:
- deduplication
- standardization
- filling or flagging missing values
- reconciling conflicting records
- validating freshness
- identifying quality issues before use
This is where many "AI-ready" claims fall apart. A model may be able to generate SQL or summarize records, but it cannot magically fix an unresolved data foundation.
For the Strategic Operator persona, this is where ROI gets won or lost. If your team is calling wrong-party numbers, routing duplicate leads, or acting on stale ownership data, the issue is not model sophistication. It’s data readiness.
3. Context and Semantics
One of the strongest ideas in the webinar was that AI needs more than facts. It needs business meaning.
A table value might be technically accurate but still misleading without context. AI needs to understand relationships, definitions, rules, and classifications that humans inside the business already know implicitly.
In a property data environment, context may include:
- how parcel IDs map across jurisdictions
- what qualifies as absentee ownership
- which signals imply motivation vs. noise
- how legal entities relate to beneficial owners
- which statuses should suppress contact
- what "vacant", "distressed", or "high equity" means operationally
This is the semantic layer many organizations skip. They give the model access to data, but not the logic needed to interpret it correctly.
That’s why some panelists argued for a "truth layer" or "system of context" between raw enterprise data and AI applications. The exact terminology matters less than the idea: AI needs governed interpretation, not just raw retrieval.
4. Governance and Access Control
Governance was the most consistent theme across the panel.
The key insight was not simply that governance matters. It was that governance must move closer to execution.
Traditional governance often lives in documents, committees, or review processes. That may be enough for periodic reporting. It is not enough for AI agents acting in near real time.
A more durable model applies governance:
- at retrieval time
- inside the data layer
- before sensitive content reaches the model
- with clear entitlements and policy enforcement
This is especially important in regulated or high-risk workflows. If an agent retrieves restricted customer or property-related data first and filters later, the damage may already be done.
For enterprise teams, that means permissions can’t be treated as a front-end issue. They must be part of the underlying retrieval and integration architecture.
5. Observability, Lineage, and Trust
If an AI system makes a recommendation or takes action, teams need to answer basic questions:
- What data did it use?
- Where did that data come from?
- Was it current at the time?
- Which rules were applied?
- Who had access?
- Can the result be audited later?
This is where lineage and observability become operational necessities rather than governance nice-to-haves.
The panel highlighted regulation as an accelerating force here. Even where requirements are still evolving, the direction is clear: organizations will increasingly need to explain how AI outputs were generated.
For data-rich operational environments, trust is inseparable from traceability.
Why Stale Data May Be Worse Than Missing Data
One speaker made a particularly useful distinction: missing context can be less dangerous than stale context.
If a system lacks information, it may fail gracefully or surface uncertainty. But if it has outdated information, it may answer confidently and incorrectly.
That’s a serious issue in property and contact workflows.
Examples:
- a property ownership change has occurred, but the model sees the prior owner
- a number appears valid but has become disconnected or reassigned
- a DNC status changed after the last sync
- a lead qualification score reflects last quarter’s conditions
- a vacancy or distress signal is no longer current
In these cases, the AI doesn’t know it’s outdated. It proceeds as if the record is accurate.
For teams focused on lead generation, outreach, underwriting, or operational automation, freshness is not just a performance metric. It’s a risk control.
The New Standard: Governance as Infrastructure
A recurring argument from the panel was that governance is evolving from a program into infrastructure.
That’s an important shift.
In the old model, governance often meant:
- review committees
- policy documents
- manual approvals
- diagrams updated infrequently
- separate teams working downstream from engineering
In the new model, governance becomes:
- machine-readable policy
- enforced permissions
- automated risk classification
- embedded approval workflows
- execution-time controls
- continuous monitoring and lineage
In plain English: good governance is no longer what you write down. It’s what your systems can enforce automatically.
For the Technical Architect, this has direct architectural implications. Pipelines, retrieval systems, and entity-resolution layers must be built so that policy can be applied programmatically. If integration is brittle or opaque, governance cannot scale.
That’s why one speaker argued that "pipeline as code" is effectively a prerequisite for "policy as code." If the movement of data isn’t programmable and testable, the rules around that movement will stay theoretical.
What This Means for AI in Real Estate and Property Data
Although the webinar spoke broadly about enterprise AI, the lessons map cleanly to real estate, PropTech, lending, and home services.
For investors and acquisition teams
You need more than a list. You need a governed, unified view of owner, property, and contactability signals. Otherwise, AI-generated lead scoring or outreach recommendations can send you straight toward dead ends.
For developers and data architects
The challenge is not just exposing data to an LLM. It’s building a retrieval and integration framework that respects:
- permissions
- lineage
- entity resolution
- low-latency delivery
- semantic consistency across sources
For operators and marketers
The prize is lower waste. Clean, unified data improves:
- right-party contact rates
- list suppression accuracy
- campaign targeting
- duplicate reduction
- workflow automation
This is where AI becomes practical. Not when it writes clever summaries, but when it helps teams act faster on clean, current, compliant records.
Common Failure Patterns to Watch For
If your organization is trying to operationalize AI, these are the red flags implied throughout the discussion:
1. Treating AI as a layer you can bolt on
If underlying systems are fragmented, AI will inherit the fragmentation.
2. Assuming a central warehouse equals trust
Centralization without entity resolution and context still produces unreliable answers.
3. Applying governance after retrieval
If the model already saw the data, the control came too late.
4. Ignoring latency
Even good data loses value if operational users or agents can’t access it fast enough.
5. Leaving business context undocumented
AI cannot infer every domain-specific rule from raw records alone.
6. Launching broad initiatives before proving one workflow
Trying to "boil the ocean" usually delays value and weakens stakeholder trust.
A Practical 12-Month Plan for Teams Building AI-Ready Data
The speakers broadly agreed on a sensible implementation pattern: start small, but start with a meaningful use case.
Here’s a practical framework inspired by the discussion.
Step 1: Pick one high-consequence workflow
Choose a workflow where better data creates measurable value.
Examples:
- owner contact resolution
- off-market lead qualification
- DNC-safe outbound routing
- property risk enrichment
- duplicate lead suppression
Step 2: Define the critical data entities
Be explicit about what must be unified.
In property workflows, that may include:
- property
- parcel
- owner
- mailing address
- phone number
- legal entity
- lead status
Step 3: Resolve duplicates and conflicts
Don’t stop at ingestion. Determine which records belong together and which values should win.
Step 4: Add business context
Document terms, decision logic, exclusions, and relationships the AI must respect.
Step 5: Enforce governance in the data path
Apply permissions and policy before retrieval reaches downstream AI tools or agents.
Step 6: Measure freshness and lineage
Track when records were updated, where they originated, and how they were transformed.
Step 7: Expand only after the first workflow works
Once one governed workflow proves value, scale to adjacent domains.
This approach fits all three BatchData personas:
- Architects reduce complexity by building one clean pattern first.
- Operators tie data work directly to measurable ROI.
- Deal-makers get faster access to accurate, differentiated opportunities.
The Strategic Bottom Line
The most valuable idea from the panel was also the simplest: AI did not create the data problem. It exposed it.
That’s why so many pilots look promising and so few create durable business value. The model gets the attention, but the real determinant is the operational quality of the data beneath it.
For teams in property, lending, home services, and enterprise risk, the takeaway is clear:
- Don’t confuse access with readiness.
- Don’t confuse centralization with unification.
- Don’t confuse governance documents with enforceable controls.
- Don’t assume AI can supply context your systems never encoded.
If you want trustworthy AI outcomes, start where the work actually lives: in integration, entity resolution, data quality, policy enforcement, and lineage.
That may sound less exciting than the model layer. But in production, it’s where the value is won.
Conclusion
AI-ready data is not a one-time cleanup project. It’s an operating model.
The organizations most likely to succeed are not the ones rushing to attach agents to every system. They’re the ones building a reliable data layer that machines can use safely and humans can trust. That means unified entities, real-time access, embedded governance, and enough context for AI to act appropriately.
In other words, the path to better AI is not more hype. It’s better data discipline - designed for speed, scale, and control.
Source: "AI-Ready Data: Building Scalable Integration and Governance Frameworks" - Reltio, YouTube, Jul 31, 2026 - https://www.youtube.com/watch?v=levBDxRdVJU