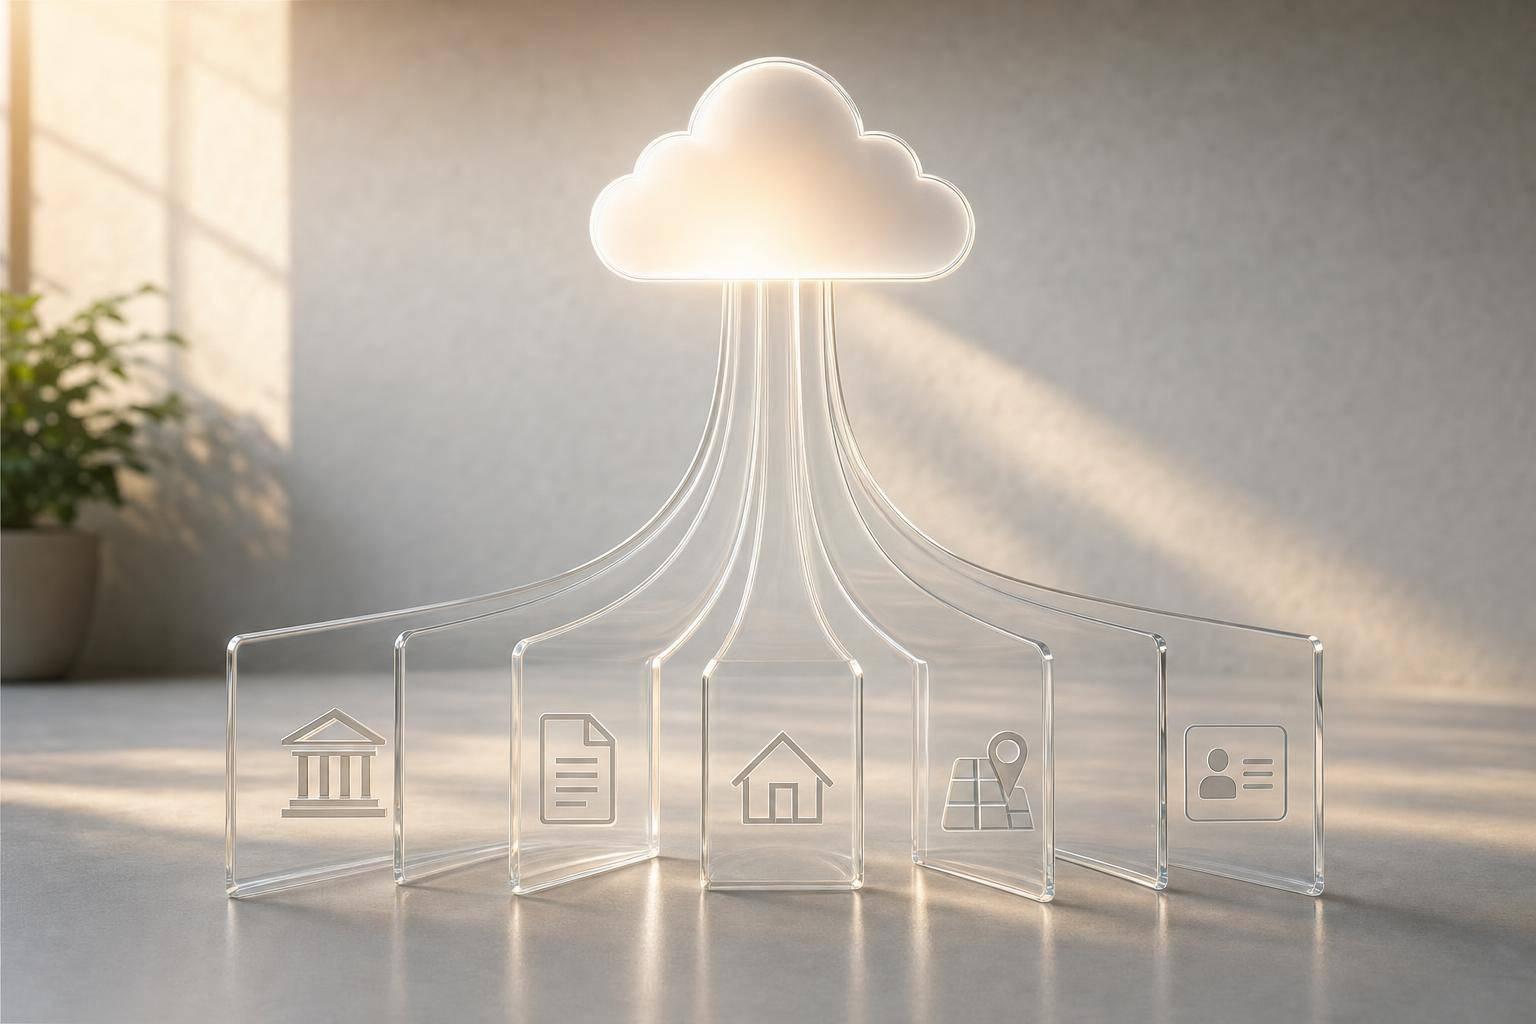
If your property data lives in five places, your team pays for it in missed matches, slow outreach, and compliance risk. I’d boil this guide down to one idea: put assessor, deed, MLS, geospatial, CRM, and contact data into one cloud pipeline, standardize the fields, match each record to one property and one owner, then control how that data is stored, updated, and used.
Here’s the plain-English version of what matters most:
- I start with the main source groups: assessor, deeds, MLS, permits, geospatial files, and internal CRM/marketing data.
- I standardize addresses, APNs, dates, owner names, sale values, lot sizes, and listing status so records can join cleanly.
- I use deterministic matching when exact keys exist, and probabilistic matching when records are messy or incomplete.
- I split the schema into property, ownership, contact, financial, compliance, and event data so each part stays easy to query.
- I store data in raw, staging, and curated layers so source files, cleanup work, and query-ready records stay separate.
- I set different update cadences by field type, because MLS status, contact data, AVMs, and deed history do not change at the same pace.
- I apply role-based access, audit logs, and inline suppression flags like DNC, TCPA, litigator, and deceased before outreach starts.
- I use the final dataset for search, skip tracing, lead scoring, and marketing, then send campaign results back into the system to improve later matches.
A few numbers stand out: the article points to 155 million+ U.S. property records, supports bulk delivery in CSV, JSON, or Parquet, and shows how teams can move from single-source lists to multi-signal targeting with owner, equity, distress, and occupancy filters in one place.
Quick comparison: fragmented setup vs. consolidated cloud setup
| Area | Fragmented setup | Consolidated cloud setup |
|---|---|---|
| Data sources | Separate tools and files | One linked cloud pipeline |
| Matching | Manual joins | Canonical property and owner IDs |
| Search | One source at a time | Multi-filter search across data types |
| Outreach | Scrubbing done later | Compliance flags attached before contact |
| Updates | Inconsistent | Scheduled by field change rate |
| Reporting | Hard to trace results | Feedback tied to source records |
So if I had to sum up the full article in one sentence, it would be this: cloud property data consolidation turns scattered real estate data into one usable system for search, contact, reporting, and risk control.
Cloud Property Data Consolidation: From Raw Sources to Activated Leads
Revolutionize Your Property Data Management with Nallas | Success Story
Map and Normalize U.S. Property Data Sources
Start with a source inventory. It shows which fields anchor a property record and which ones need cleanup, mapping, or regular refreshes. Skip this step, and your joins can fall apart fast - especially once county-by-county quirks show up.
Core Source Categories: Assessor, Deeds, MLS, Permits, and Internal Systems
County assessor and deed filings set the baseline for 150 million+ U.S. property records. These sources supply the stable fields that hold the record together: Assessor Parcel Number (APN), property class, land use, year built, total building area, and lot size. Deed and mortgage records add transaction history, including last sale price, sale date, mortgage amount, and ownership type.
A simple way to think about it: assessor and deed data are the anchors. MLS and CRM data are the faster-moving layers on top. MLS feeds change often. Permit records are another public source many teams track alongside assessor, deed, and MLS data. Geospatial data - such as subdivision names, situs address, mailing address, latitude/longitude, and custom boundary polygons - helps with address matching and territory mapping. Internal systems, especially CRM and marketing platforms, add contact details like phone numbers and email addresses.
| Source Category | Essential Fields for Consolidation |
|---|---|
| Assessor/Tax | APN/Parcel ID, Property Class, Land Use, Year Built, Total Building Area, Lot Size (Acres/Sq Ft) |
| Deeds/Mortgage | Last Sale Price, Sale Date, Mortgage Amount, Transaction History, Ownership Type (LLC, Trust, Individual) |
| MLS & Listings | Listing Status (Active/Pending/Sold), Days on Market, Price per Sq Ft |
| CRM/Marketing | Phone Numbers (with Line Type/Carrier), Email Addresses, Name Aliases, DNC/TCPA Flags, Owner-of-Record Flag |
| Geospatial | Subdivision Name, Situs Address, Mailing Address, Latitude/Longitude, Custom Boundary Polygons |
Next comes standardization. If the same field means one thing in one system and something slightly different in another, matching gets messy in a hurry.
Normalization Rules for Addresses, Dates, Values, and Property Attributes
Raw county data rarely arrives in a clean, matching format. That’s why normalization matters. It turns separate records into records you can actually join.
Break every address into standard parts: street, city, state, ZIP, ZIP+4, and county. Then verify that the address is valid. Use the APN, or a canonical property ID, as the anchor key.
For values, store both the absolute sale price in USD and the calculated price per square foot. A $450,000 sale does not mean the same thing in every market, so price per square foot gives you a better comparison point. Lot size should live in both acres and square feet, because counties and listing feeds often provide only one or the other. Store sale dates in mm/dd/yyyy format to support hold-period and trend analysis.
Owner names should be stored as first, middle, and last, along with aliases and an owner-of-record flag across individuals, corporations, trusts, and LLCs. MLS status fields should also map to a fixed vocabulary - sold, active, pending, failed, off-market - no matter how the source labels them.
"A comparison asks something specific: which nearby properties are close enough to this one to say what it is worth? Answering it takes a particular set of details: how big, how old, what type, what it last sold for, and not much else." - Jesse Burrell, CEO and Co-founder, BatchData
These normalized fields become the input for record matching and the canonical schema.
Ingestion Patterns: Batch ETL, APIs, and Change-Based Refreshes
Pick your ingestion method based on how often the field changes and how the data will be used. Batch ETL through SFTP in CSV, JSON, or Parquet is a good fit for assessor records, tax rolls, and deed history, where monthly or quarterly refreshes are enough. Real estate API syncs work better for near real-time needs, like instant property lookups, inbound lead qualification, and identity resolution for unknown contacts. Change-based refreshes make sense for fields that shift often but do not need full reloads, such as listing status and pricing.
It also helps to build backup sources in from day one. If a county feed is late, you don’t want a hole in the record set. During ingestion, append DNC, TCPA, litigator, and deceased signals as well.
Those ingestion patterns then feed storage, refresh cycles, and access control.
Match Records and Design a Canonical Property Schema
Normalized data only starts to pay off when you can tie records back to one property and one owner. That’s what gives you the canonical IDs your storage layer will use for refresh, access, and activation.
Deterministic and Probabilistic Matching for Property and Owner Identity
Start with deterministic matching. If a parcel ID, APN, document number, or normalized address shows up in both the assessor file and the deed record, an exact-match join usually links them cleanly.
The trouble starts when those keys are missing or don’t line up. And that happens a lot once MLS feeds, CRM exports, or inbound lead forms get mixed in.
When exact keys don’t work, switch to probabilistic matching. Now you’re not working from one clean identifier. You’re comparing owner names, mailing addresses, geocodes, or phone numbers that may be a little off. Modern identity resolution systems can return ranked matches based on match strength, which helps deal with shared phone lines, households, and reassigned numbers.
| Feature | Deterministic Matching | Probabilistic Matching |
|---|---|---|
| Primary Inputs | Parcel IDs, APNs, Document Numbers, Normalized Addresses | Owner Names, Mailing Addresses, Geocodes, Phone/Email |
| Accuracy | High; relies on exact unique keys | Variable; relies on match strength scores |
| Compute Cost | Lower; simple index lookups | Higher; requires scoring and ranking algorithms |
| Best Use Case | Linking assessor records to deeds | Resolving inbound leads with messy contact data |
Some fields also need a little wiggle room. Bedrooms or living area, for example, should match within a tolerance band instead of by exact value. That lets your logic handle small differences across records without splitting what is almost certainly the same property.
Conflict Resolution and Deduplication Across Source Systems
When two sources disagree on a field, set source-priority rules and keep lineage for every value. In plain English: don’t overwrite data blindly.
Keep the original value, keep the source that supplied it, and make the origin clear. Sale date and hold period should also be tracked as lineage fields. They help you tell the difference between a real ownership change and a feed that’s just behind.
An owner-of-record flag also helps. It marks the current legal entity tied to the property, which matters when deed history includes prior owners or occupants who should not be treated as the current owner.
Schema Design for Property, Owner, Contact, and Event Tables
Once matching is done, use those IDs to split stable property data from owner, contact, financial, compliance, and event data. The goal is simple: one record per property and one record per owner across systems, with each core module kept separate but easy to join.
| Module | Key Fields | Primary Use Case |
|---|---|---|
| Property Core | APN, Situs Address, Mailing Address, County, ZIP+4, Beds/Baths, Sq Ft, Year Built, Pool | Search & Filtering |
| Ownership | Owner Name, Aliases, LLC/Trust Indicator, Ownership Type, Owner-occupancy Status | Segmentation & Legal Outreach |
| Contact | Phone (Ranked, Line Type, Carrier, Reachability), Email (Ranked, Deliverability) | Skip Tracing & Outreach |
| Financials | Last Sale Price, Sale Date, Price/Sq Ft, AVM, Equity Estimate | List Building & Valuation |
| Compliance | DNC Flag, TCPA Flag, Litigator Indicator, Deceased Indicator | Risk Mitigation |
| Events | Listing Status, Foreclosure Date, Permit Type, Campaign Outcome | Reporting & Feedback |
This schema is the handoff point for storage, refresh, and controlled access. For reporting and API delivery, keep every module joinable through a canonical property ID, then return only the fields each use case needs.
"An agent doesn't want a hundred fields it has to reason its way through. It wants the ones the question actually needs." - Ivo Draginov, President, BatchData
Store DNC, TCPA, litigator, and deceased flags in the contact record so suppression happens before outreach.
Build the Cloud Storage, Refresh, and Access-Control Layer
Once records are matched and standardized, the next step is deciding how to store them, update them, and make them available without creating a mess.
Raw, Staging, and Curated Storage Layers for High-Volume Property Data
Use a three-layer cloud storage setup: raw, staging, and curated.
Raw stores original feeds exactly as they arrive. Staging is where normalization and matching take place. Curated stores the clean property and identity records your teams actually query and use.
This split matters because records come in from assessor, deed, MLS, permit, and internal feeds. By keeping raw and curated separate, late-arriving feeds don't hold up downstream use. The curated layer then supports property search and analytics from one interface.
Think of it like a prep kitchen. Raw is the delivery dock, staging is the workbench, and curated is the plated meal that goes out to the table.
Refresh Schedules Based on Field Change Rate
Not every field needs the same update schedule. A tiered cadence keeps data current without putting extra strain on your systems.
| Data Type | Recommended Cadence | Reason |
|---|---|---|
| Automated Valuation Models (AVMs) | Monthly | Valuation changes quickly |
| Portfolio revaluation | Event-based (as new sales land in a neighborhood) | Mark holdings to market on neighborhood movement |
| Propensity scores (such as BatchRank) | Real-time | Machine learning scores hundreds of signals quickly |
| Market research | On demand | Best for benchmarks and turnover trends |
| Contact enrichment | Real-time / inbound | Useful for unknown callers and lead form submissions |
Match the refresh cadence to the field and the workflow, whether that's valuation, prospecting, search, or outreach. If a workflow only needs a valuation or a comp, ask for a focused property enrichment payload instead of the full property record.
Fresh data is nice. Usable fresh data is what counts.
Role-Based Access, Audit Logs, and Contact-Data Compliance
Consolidated property and contact data should follow least-privilege access. In plain English, each role should get only the fields it needs. Compliance signals should stay attached to the contact record so suppression happens before outreach, not after.
You also need a clear line around use. This data should support property operations, not FCRA-covered eligibility decisions . That line should live in your governance policy and in your access rules.
The same curated layer can power search, skip tracing, and marketing. Expose it through REST APIs, and keep identity and property graphs in the same environment so a workflow can resolve unknown contacts to specific assets in a single call .
Activate Consolidated Data for Search, Skip Tracing, and Marketing
Property Search and Lead Selection from a Single Source of Truth
Once canonical IDs and curated storage are set up, the next step is activation. At that point, your dataset becomes the layer your team searches, filters, and sends into outreach.
A consolidated cloud dataset lets your team filter for ownership, equity, distress, and occupancy in a single query, using matched property and owner IDs. That matters because it makes overlap analysis much easier. Instead of checking one list at a time, you can spot properties showing multiple distress signals at once, like high equity, vacancy, and tax default. Those stacked signals are often where conversion rates go up.
You can tighten results with tolerance bands and custom polygons so searches fit local property patterns and market lines. Then add one more layer: AI-driven propensity scoring. BatchData's BatchRank reviews hundreds of data points to score likely sale intent before a property hits the market, which helps your team spend more time on high-intent leads instead of working cold inventory.
Those same search filters can move straight into skip tracing for verified outreach lists.
Skip Tracing Pipelines with Enrichment, Verification, and Clean Outputs
Skip tracing takes a property and owner list and turns it into contact records your team can actually use. The big difference between a clean file and a messy one usually comes down to where compliance scrubbing happens.
BatchData returns DNC registry flags, TCPA indicators, litigator status, and deceased indicators inline with the contact record, not as a separate step. That means only cleaner contacts move into your dialer or CRM. Outputs also include line type, carrier, reachability, deliverability, mailing addresses, and up to three ranked matches.
There’s also a reverse workflow. Reverse Skip Trace can resolve an unknown number to the likely owner and linked property in one API call, which helps acquisitions teams qualify a caller live. For large campaigns, bulk delivery is available through SFTP in CSV, JSON, or Parquet. For live workflows, RESTful JSON APIs handle the job.
Billing is metered by matched records returned, not total API calls sent. So if you’re testing a weak list, you’re not getting charged for every probe that goes nowhere.
The same verified output should pass straight into your CRM, dialer, and direct mail systems.
Marketing Activation, Feedback Loops, and Key Takeaways
After records are enriched, push them into downstream tools and tie response data back to the source records. Track deliverability, contact rates, offer acceptance, and cost per contact against the original property and owner entries. That shows your team which lead signals convert and which refresh schedules are worth paying for.
Here’s how the core workflow changes:
| Metric | Fragmented Lists | Consolidated Enriched Data |
|---|---|---|
| Search Depth | Limited to single-source filters (e.g., just tax records) | Multi-filter: ownership, equity, distress, occupancy |
| Identity Linkage | Manual owner-to-phone matching | Automated reverse skip trace in one API call |
| Compliance | Secondary scrubbing vendor required | Inline DNC, TCPA, and litigator flags |
| Lead Scoring | Basic sort by date or value | AI propensity scoring via BatchRank |
Teams that perform well usually send CRM results back into the enrichment process. That loop helps improve match quality and refresh timing over time. In plain English, the more your team learns from outcomes, the better future search, scoring, and enrichment choices become.
FAQs
How do I start consolidating property data?
Start by defining what your business needs most. That could be lead sourcing, market analysis, or automated valuation.
Then use BatchData to pull together U.S. property records in one place. The platform includes ownership, mortgage, transaction, and contact data.
You can connect to the data through RESTful JSON APIs for:
- Single-address lookups
- Large-scale delivery
- Synchronous requests
- Asynchronous requests
- Bulk delivery
Which fields should I standardize first?
Start with the fields that make records easy to compare and sort: core property identifiers like situs and mailing addresses, along with key details such as bedroom and bathroom count, living area, year built, lot size, and story count.
It also helps to standardize derived metrics like price per square foot and hold period. That way, your analysis stays consistent across markets.
How often should property data be refreshed?
Refresh frequency should match your use case and what you need from the analysis. Some datasets, like Automated Valuation Models, update monthly. Others, such as market research and institutional portfolio tracking, may need updates as often as your analysis demands.
For contact data and lead management, the right refresh cycle depends on the quality and accuracy of the records you already have. BatchData recommends reviewing file performance to figure out the best update schedule.