Most organizations do not have a data shortage. They have an alignment problem.
That was the central lesson from a workshop on direct care workforce data strategy: the hard part is not finding more data, but figuring out whether the data you already have can answer the workforce questions that matter. For teams responsible for operations, policy, or systems design, that distinction is critical.
This is especially relevant to anyone managing fragmented records across agencies, vendors, surveys, and compliance systems. Whether you work in direct care, PropTech, home services, or any other data-heavy sector, the pattern is familiar: multiple sources exist, stakeholders have urgent questions, and yet decision-makers still lack clear answers.
The workshop focused on state systems working to strengthen the direct care workforce, but its framework travels well. The underlying idea is universal: data infrastructure should support decisions, not just reporting.
Key Takeaways
- Start with business questions, not data inventories. A source is only useful if it helps answer a priority workforce question.
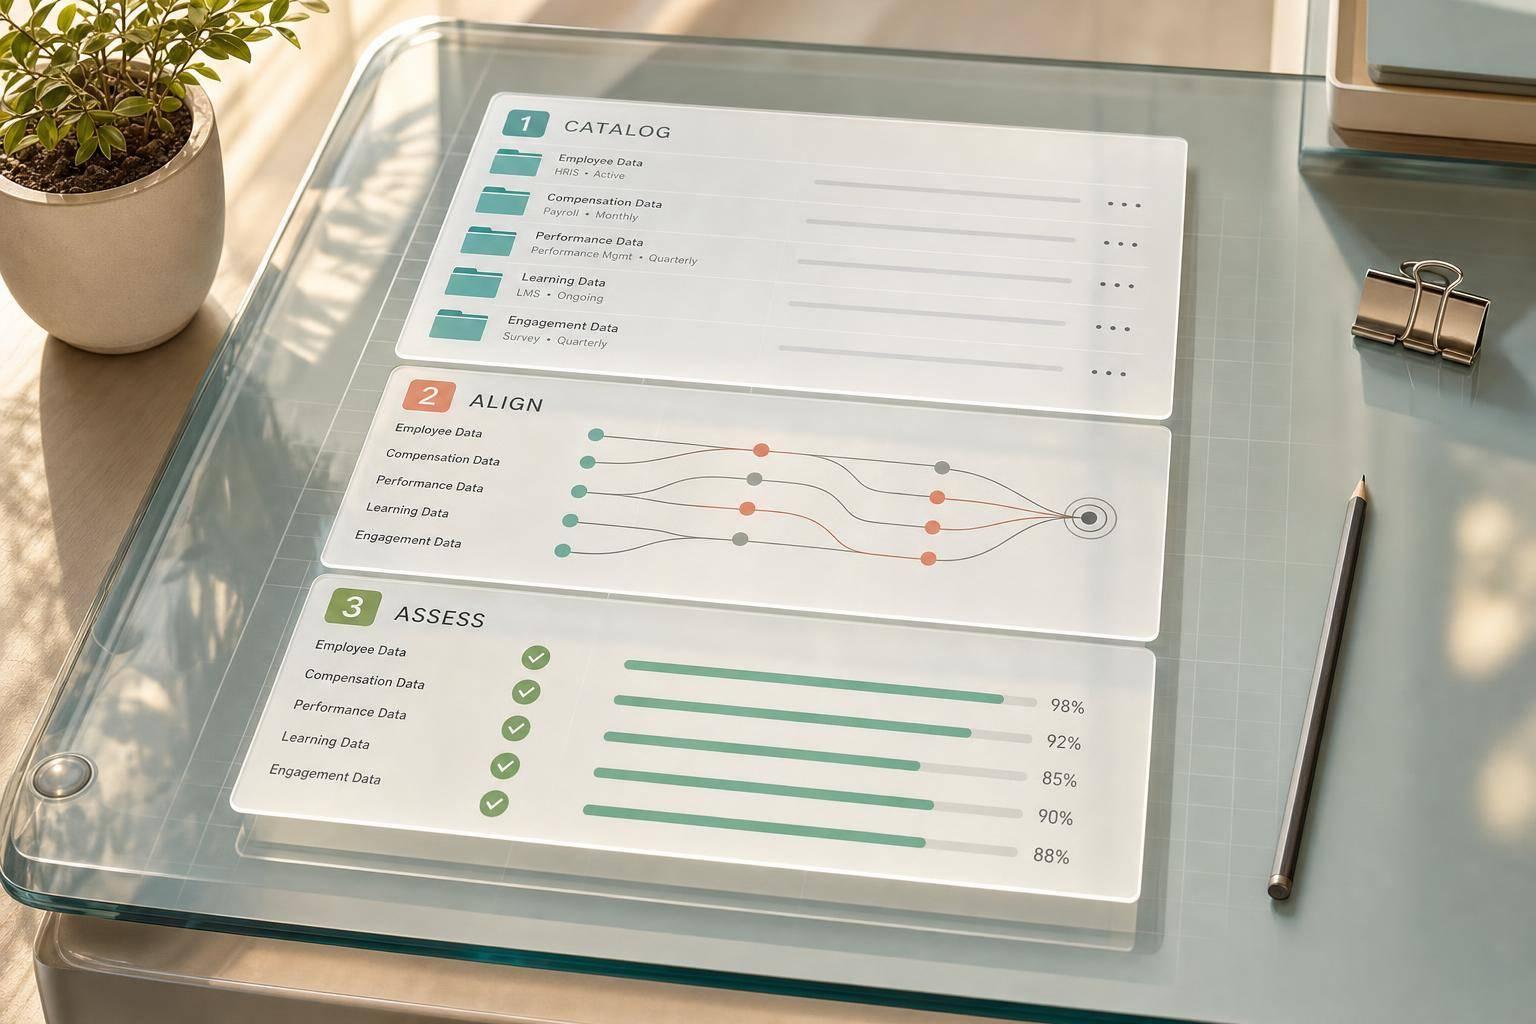
- Catalog data systematically. Document ownership, coverage, fields, timeliness, quality, linkage potential, and access constraints.
- Do not confuse existence with usability. Knowing a dataset exists is not the same as understanding what it can reliably support.
- Score data sources against your goals. Evaluate coverage, content, quality, timeliness, and integration potential in relation to actual use cases.
- Treat gaps as strategy signals. Missing fields, populations, or stale records show where your infrastructure needs work.
- Prioritize by impact and feasibility. Focus first on changes that materially improve decisions without creating heavy reporting burden.
- Use existing operational systems where possible. Kansas showed that systems built for another purpose, like EVV, can become valuable workforce intelligence assets.
- Avoid duplicate collection. More surveys and forms do not always mean better insight; they often create provider fatigue.
- Cross-functional coordination matters. Data, policy, operations, and program teams need shared definitions and shared priorities.
- The goal is not perfect data. The goal is transparent, decision-ready data that improves over time.
The Real Shift: From Data Collection to Data Strategy
The workshop’s lead presenter, Julie Bershotzky of the University of Minnesota, framed the issue clearly: many teams get stuck after identifying stakeholders, defining the workforce, and listing possible data sources. That groundwork is necessary, but it does not produce a functioning data strategy on its own.
The next step is more disciplined. Instead of asking, What data do we have?, the better question is:
Is our data set up to answer the workforce questions we actually care about?
That sounds simple, but it changes everything.
A reporting-first mindset tends to produce scattered spreadsheets, one-off surveys, and isolated administrative records. A strategy-first mindset asks whether those inputs can support decisions around recruitment, retention, compensation, coverage, turnover, or unmet need.
For technical architects, this resembles a familiar systems problem: you can have plenty of endpoints and still lack a usable architecture. For operators, it looks like a performance problem: teams spend money gathering information that does not move outcomes.
Step 1: Build a Real Catalog of Your Data Sources
A proper catalog goes beyond naming datasets. It creates a structured view of what each source is, why it exists, and what it can do.
The workshop laid out several categories worth documenting.
1. Administrative details
Start with the basics:
- Name of the data source
- Owning agency or team
- Original purpose of collection
- Legal or regulatory basis, if applicable
- Responsible contact or steward
This matters because datasets are often created for reasons unrelated to your current use case. If you do not understand the original purpose, you can easily overinterpret the data or underestimate the effort needed to change it.
In modern data operations terms, this is governance. If nobody knows who owns a source, who defines its fields, or who can approve access, integration stalls fast.
2. Population and coverage
This is where many organizations make costly assumptions.
Document:
- Which programs are included
- Which settings are covered
- Which worker types appear in the data
- Geographic scope
- Whether the source is sample-based or population-based
A dataset may feel comprehensive while only covering a narrow slice of reality. For example, it might include only licensed providers, only certain counties, or only Medicaid-funded services. If you make workforce decisions as if it covers the entire market, your conclusions will be distorted.
For operators, this is the equivalent of relying on lead data from one channel and assuming it represents your full pipeline.
3. Workforce data elements
Next, map the actual fields available. Do not stop at broad labels like "worker data." Get specific.
Possible categories include:
- Workforce size and composition
- Vacancies
- Turnover and retention
- Compensation and benefits
- Training and credentials
- Worker demographics
- Worker experience or satisfaction
This is often where misalignment becomes visible. If leadership wants to know whether low pay is driving turnover, but no source captures pay or turnover consistently, the question cannot be answered yet. That is not a failure of analytics. It is a gap in source design.
4. Data characteristics
You also need to understand how the data behaves:
- Is it administrative, survey-based, claims-based, or something else?
- What is the unit of analysis: worker, provider, claim, visit?
- How often is it collected?
- How current is the latest cycle?
Timeliness matters more than teams sometimes admit. A clean dataset that is four or five years old may support historical analysis, but it is weak for operational decisions.
For fast-moving teams, stale data is not just inconvenient. It creates false confidence.
5. Data quality and limitations
No source is perfect. The workshop emphasized that the goal is not perfection but clarity.
Assess:
- Completeness of key fields
- Accuracy
- Validation practices
- Consistency of definitions over time
- Known gaps and caveats
This point deserves emphasis. Data fields often drift. Definitions change. Submission behavior varies by provider or region. If those shifts are not documented, trendlines can become misleading.
Strong data strategy means being honest about limitations early instead of discovering them after a board presentation or policy decision.
6. Linkage and integration potential
This is where raw data starts becoming infrastructure.
Ask:
- Can the source connect to other datasets?
- Is there a unique identifier?
- If not, can one be constructed?
- Does it overlap with other systems?
- Can it be exported in analyzable formats?
If your data lives in disconnected systems, your answers will remain partial. This should sound familiar to any developer who has inherited disconnected APIs or to any operations team forced to reconcile multiple versions of the truth.
7. Access and use constraints
Finally, document the practical barriers:
- Who can access the data today?
- How is it currently used?
- Does it contain personally identifiable information?
- What is the reporting burden?
- What does collection or maintenance cost?
Sometimes the biggest obstacle is not missing content. It is governance friction, privacy constraints, or provider fatigue.
That matters because even good ideas fail if the collection burden is too high or the approval path is too complex.
Step 2: Evaluate Each Source Against the Questions You Need to Answer
Once you have a real catalog, the next move is not immediate integration. It is evaluation.
The workshop recommended judging each source across several dimensions:
- Coverage
- Content
- Quality
- Timeliness
- Integration potential
The important nuance is this: score the source in relation to your key workforce questions, not in isolation.
That distinction is what turns inventory into strategy.
A dataset can be high-quality in a technical sense and still be low-value for your use case. Conversely, a somewhat messy operational system may be extremely valuable if it captures a workforce behavior no other source shows.
A simple scoring model works
The presenter suggested a practical scoring process rather than an overly academic one. Teams can rate each dimension on a simple scale such as:
- Poor
- Inconsistent
- Generally reliable
- Strong
The point is not statistical precision. The point is to force useful discussion.
Scoring creates:
- Shared language across teams
- Faster comparison across sources
- Visibility into tradeoffs
- Clearer prioritization for improvement
For a technical audience, think of this like a readiness assessment for production use. For an operations audience, it is a decision matrix that helps avoid wasting budget on low-impact data efforts.
Step 3: Turn Low Scores Into a Gap Map
This is the moment many teams find uncomfortable: once you score your sources honestly, the holes become obvious.
That is a good sign.
As the workshop noted, visible gaps mean you are making progress. Hidden gaps create bad decisions; explicit gaps create a roadmap.
Common types of gaps
Low-scoring dimensions often point to specific issues such as:
- Missing data elements
- Missing populations
- Missing service settings
- Geographic blind spots
- Time lag
- Low completeness
- Unclear definitions
The right response is not to label the system "bad." It is to ask two questions:
- Why does this gap matter?
- How does it limit our ability to answer priority questions?
This keeps teams from trying to solve everything at once.
Not all gaps deserve the same urgency. Some are strategic; others are noise.
Step 4: Diagnose Root Causes Before Designing Fixes
Once gaps are identified, the workshop recommended tracing them back to root causes.
That can include:
- Policy constraints
- Technology limitations
- Cost
- Reporting burden
- Weak coordination across organizations
- Inconsistent definitions or standards
This is where mature teams separate symptoms from causes.
For example:
- If turnover cannot be measured, is the issue a missing field, inconsistent provider submissions, or an inability to link worker records across time?
- If vacancy data is stale, is the problem lag in collection, manual processing, or low submission compliance?
- If a population is invisible, is that because the program is out of scope or because systems were never designed to capture it?
Without root-cause analysis, organizations tend to default to "collect more data", which often creates more burden without improving visibility.
Step 5: Prioritize Improvements by Impact and Feasibility
The workshop’s final strategic step was prioritization.
This is where a data roadmap becomes realistic.
High-impact, lower-effort improvements
Some fixes are relatively achievable, such as:
- Aligning definitions across systems
- Cleaning key fields
- Clarifying submission requirements
- Standardizing identifiers
- Reducing duplicate survey questions
These are often the fastest wins because they improve usability without requiring a brand-new platform.
High-impact, long-horizon improvements
Other fixes are structural:
- Creating an integrated workforce registry
- Building a new statewide data collection system
- Establishing long-term governance and ownership models
- Reworking vendor or managed-care reporting requirements
These can be worthwhile, but they require funding, political support, and sustained execution.
The recommended filter was straightforward:
- Impact on key workforce questions
- Feasibility, including cost, time, burden, and political will
That is a disciplined way to move from "we have data problems" to "we have a phased strategy."
What Kansas Adds to the Conversation
The workshop became especially useful when Kansas shared how this work plays out in practice.
Their case reinforces a reality many data teams know well: alignment rarely happens automatically. Even when multiple groups care about the same issue, initiatives often launch in parallel, using different assumptions and timelines.
Kansas used ARPA funding to support workforce-related projects tied to training and career ladder development. To inform those efforts, the state and research partners at the University of Kansas analyzed multiple inputs, including:
- Electronic Visit Verification (EVV) data
- Bureau of Labor Statistics data
- New workforce surveys
That mix is notable. It combines administrative records, public labor data, and primary research rather than overrelying on any single source.
Why the EVV Example Matters
The most instructive part of the Kansas presentation was its use of EVV data.
EVV systems were built for compliance and service verification, not as workforce intelligence platforms. But Kansas treated the system as a potentially rich operational dataset. That is an important mindset shift.
For any data-driven organization, this is a familiar move: a system designed for one operational purpose may become strategically valuable when evaluated differently.
What Kansas found
Using 2024 EVV records from its vendor system, Kansas analyzed a dataset that included:
- More than 27,000 service participants
- About 25,000 direct support workers
Several insights stood out:
- More than 77% of the home-based workforce in the dataset was self-directed
- The number of people using self-directed services was growing faster than the self-directed workforce
- A one-year turnover estimate came in around 38%, with agency-based settings showing higher turnover than self-directed settings
Even without overgeneralizing, these findings matter. They sharpen planning priorities. If most of the workforce is self-directed, then workforce initiatives that ignore that segment will miss the majority of the labor pool.
That kind of insight is exactly why source alignment matters.
The limitations were just as important
Kansas did not present EVV as perfect. In fact, the limitations may be the most useful lesson.
The presenters noted that EVV only covered:
- HCBS-funded workers
- Home-based settings
It did not capture direct support workers in residential or day-service settings. They also ran into data anomalies that limited some planned analyses, including efforts to estimate unfilled care hours.
This is a strong example of responsible data practice. Instead of overselling the source, the team explained what the data could and could not support. That transparency builds trust and protects downstream decision-making.
A Better Lesson Than "Collect More Surveys"
Kansas also used survey data to understand worker experience, including job satisfaction, training needs, retention, and career goals.
One especially useful finding came from a behavioral economics survey that asked workers to rate job factors by importance and satisfaction. The broad takeaway: workers were more satisfied with the intrinsic parts of the job, such as meaning and relationships, than with the structural parts, such as pay and benefits.
That result will not surprise most operators, but it does provide evidence for something often discussed anecdotally: mission helps retention, but compensation still matters.
More importantly, Kansas did not treat surveys as the default answer to every data gap. The presenters were explicit that future efforts should reduce duplication and avoid overburdening providers. That is exactly the right instinct.
If a field can be sourced reliably from an operational system, asking for it again in a survey may be unnecessary.
The Operational Challenge: Alignment After Funding
One of the most realistic parts of the discussion came during Q&A. After initial funding ended, Kansas faced a common problem: how to sustain collaboration, analysis, and ownership when dedicated project staffing decreases.
That issue is bigger than direct care. It is a recurring pattern across enterprise data work.
Pilot efforts often succeed because they have:
- Focused funding
- Dedicated staff
- Executive attention
- Narrow scope
The challenge begins when teams try to operationalize the work across managed care organizations, agencies, external quality review groups, and providers.
Kansas appears to be navigating this by:
- Aligning managed care organization efforts
- Considering ongoing stakeholder surveys
- Exploring a web-based workforce registry
- Looking for ways to use quality oversight structures without duplicating collection burdens
The lesson here is practical: good data strategy needs a post-pilot operating model. Otherwise, useful analysis fades once the initial project window closes.
What Technical and Operations Leaders Can Learn From This
Even if your domain has nothing to do with direct care, the workshop offers a clear blueprint for handling fragmented business-critical data.
For technical leaders
The biggest takeaway is that source alignment should happen before large-scale integration work.
Do not start by building pipelines for everything. First determine:
- Which sources are decision-critical
- Which fields are trustworthy
- Which IDs can support linkage
- Which governance issues will block adoption
That saves engineering time and reduces the risk of building elegant infrastructure around weak inputs.
For operations leaders
The biggest takeaway is that bad decisions often come from false assumptions about coverage and quality.
Before acting on dashboards or reports, ask:
- What population does this actually represent?
- How current is it?
- Are definitions stable over time?
- Are we measuring the workforce we think we are measuring?
Those questions can prevent wasted spend, poor staffing decisions, and reporting that sounds precise but is strategically weak.
A Practical Framework You Can Apply
If you want to borrow the workshop’s approach for your own organization, this is the simplest version:
1. Define your priority questions
Examples:
- Where is turnover highest?
- Which worker segments are hardest to retain?
- Are pay or benefits correlated with exits?
- Where are service gaps increasing?
2. Inventory every relevant data source
Include systems you already use operationally, not just formal reporting tools.
3. Catalog each source consistently
Capture governance, coverage, fields, quality, timeliness, integration, and access.
4. Score sources against your questions
Use a simple rubric. Make the strengths and weaknesses explicit.
5. Identify the meaningful gaps
Focus on the missing pieces that block important decisions.
6. Investigate root causes
Separate fixable process issues from larger structural barriers.
7. Prioritize a phased roadmap
Balance impact, burden, cost, and feasibility.
This is not glamorous work, but it is the kind of discipline that turns fragmented records into reliable operational intelligence.
Conclusion: Better Workforce Decisions Start With Better Alignment
The strongest idea from the workshop is also the most transferable: data is not the goal.
The goal is answering important questions well enough to make better decisions.
That means understanding your sources deeply, evaluating them against real decision needs, acknowledging their limits, and improving them in a deliberate sequence. Kansas showed that even imperfect systems can generate meaningful insight when teams are willing to look beyond original use cases and coordinate across silos.
For any organization trying to build a modern data operation, that is the real takeaway. You do not need to begin with a perfect system. You need to begin with a clear question, an honest inventory, and a practical plan for turning disconnected data into decisions you can trust.
Source: "DCW Strategies Center Workshop: Identifying and Aligning Data Sources and Understanding Gaps" - Administration for Community Living, YouTube, Jul 31, 2026 - https://www.youtube.com/watch?v=Lua9jnSPfAg